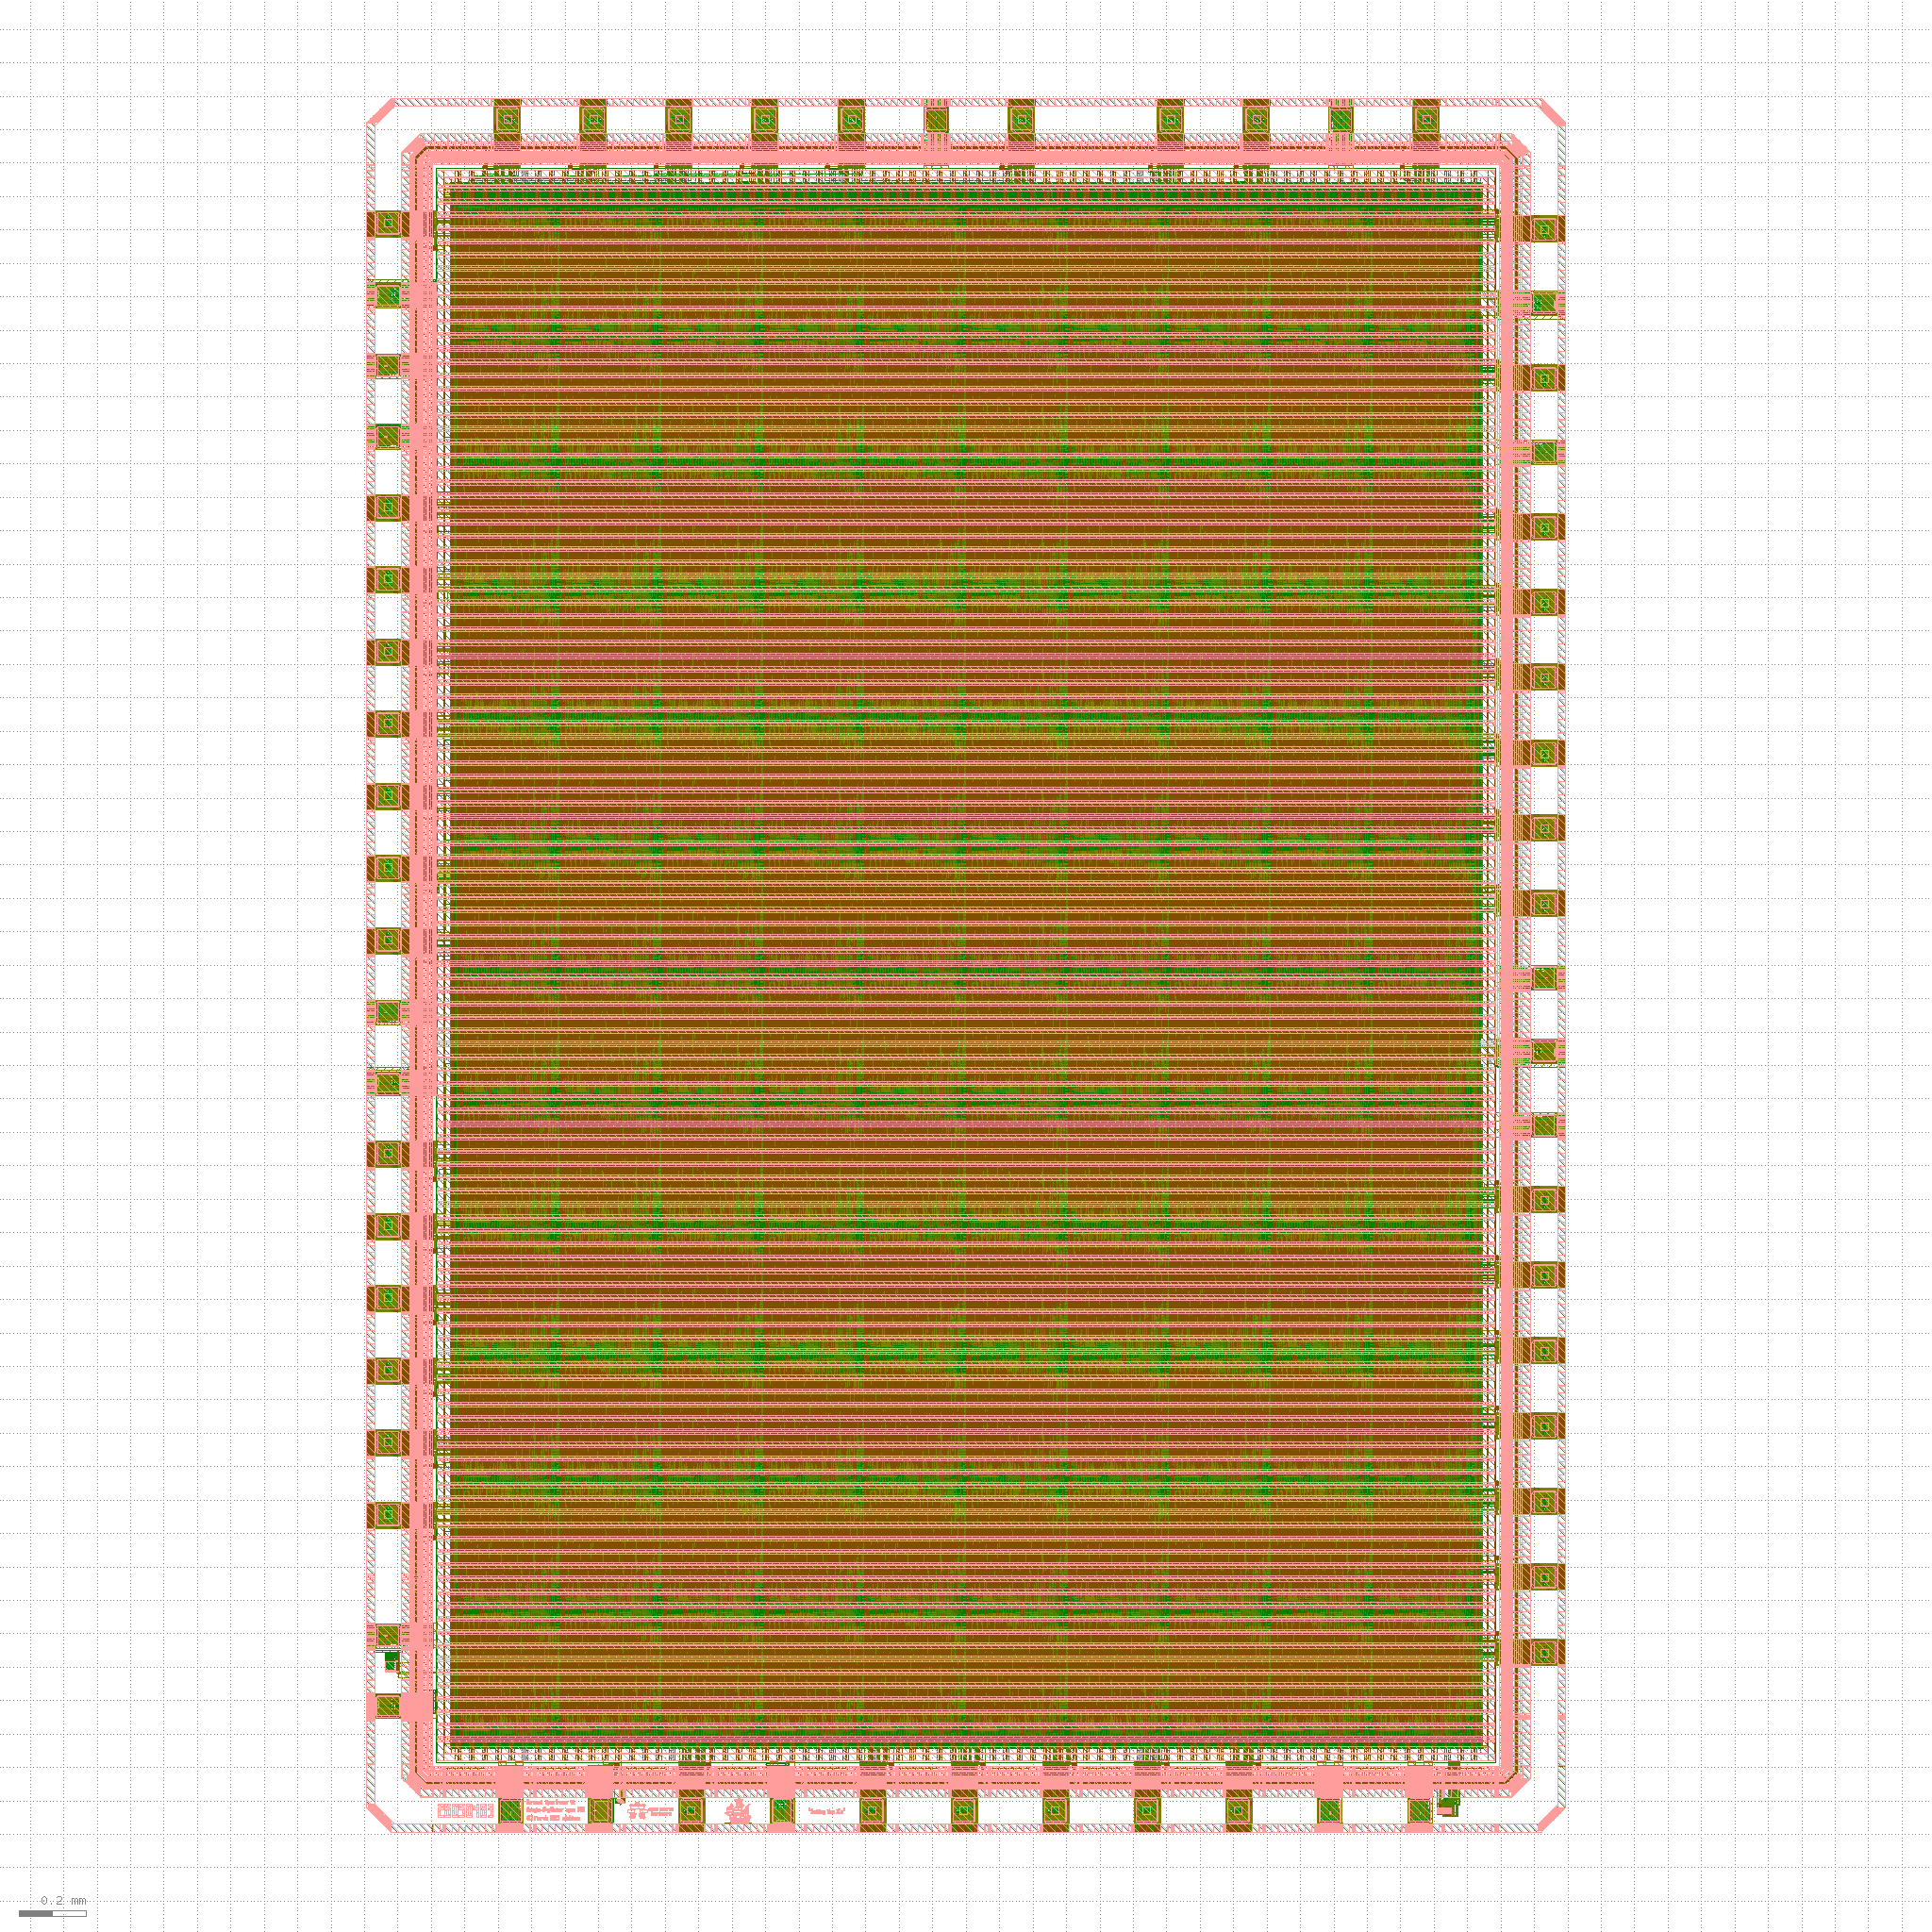
A homogeneous array of self-timed compute cells with no global clock. Only the cells doing work draw power. You program it by drawing a GNU Radio flowgraph, not by writing HDL, and every tool you need is open source and free. The first chip, a 120-cell test chip on SkyWater SKY130, is in fabrication now to prove the asynchronous architecture on real silicon.
The best 20 minutes on Kyttar: the architecture, the chip, the software, and the results, as presented at the GNU Radio Conference 2026 in Raleigh on September 23.
What SDR engineers asked about most at GRCon: the jobs an FPGA does today in radios, done differently.
No clock and no clock tree, so a cell with no data moving draws only leakage. Power follows activity instead of sitting on a clock-tree floor. Measured per cell in SPICE on SKY130: about 2.4 mW executing and about 90 nW quiescent.
Draw the flowgraph in GNU Radio Companion. Each block becomes a region of cells and each connection a route. No HDL, no synthesis, no timing closure: placement and routing take seconds, and the output comes back into GNU Radio.
placeKYT, the simulator, the GNU Radio module and the block library are open source and free. No license server and no paid tool tier, ever: buying the hardware should be the only cost of using it.
There is no head-to-head against an FPGA yet, and there shouldn't be: this first chip is a 130nm test chip, and comparing it with an FPGA on a modern node would be apples to oranges. Its job is to prove the asynchronous architecture works on silicon before capital goes into a smaller node with a partner.
Seven complete software-defined radios, four digital modems and three analog transceivers, each placed, routed, and running end to end on one 120-cell Kyttar array. Verified against GNU Radio; digital modems recover at BER 0. These are measured cycle-accurate simulation numbers; first silicon returns at the end of November 2026.
| Design | RX rate | RX power | TX rate | TX power |
|---|---|---|---|---|
| BPSK | 188 kSa/s | 9.6 mW | 481 kSa/s | 7.6 mW |
| QPSK | 172 kSa/s | 8.2 mW | 460 kSa/s | 9.1 mW |
| 4FSK | 542 kSa/s | 15.2 mW | 225 kSa/s | 4.2 mW |
| 16-QAM | 146 kSa/s | 8.9 mW | 460 kSa/s | 11.5 mW |
| AM | 460 kSa/s | 10.1 mW | 479 kSa/s | 5.9 mW |
| FM | 1.93 MSa/s | 6.3 mW | 429 kSa/s | 5.7 mW |
| SSB | 346 kSa/s | 14.0 mW | 346 kSa/s | 14.4 mW |
Because the fabric is asynchronous, only the cells doing work draw current, so every design idles at roughly half a milliwatt and runs at single-digit to low-double-digit milliwatts when active. FM demodulation runs at 1.93 MSa/s on just three active cells. Since idle cells cost essentially nothing, several of these radios run in parallel on one die and only the busy ones burn power. Simplex, driven at saturation.
Three steps from a block diagram to a running design: no hardware-description language, no timing closure, no manual layout.
Compose your signal chain in GNU Radio Companion using Kyttar DSP blocks, the workflow SDR engineers already know.
Import it into placeKYT. It maps your block graph onto the 2D cell array, routes it, and builds a bitstream automatically.
Simulate it cycle-accurately against real signal data and watch every cell execute. Breakpoints, single-step and live register inspection are in progress.
The whole point is a shorter, more transparent loop. You see exactly what your design does on the hardware, because the thing you debug is the thing that runs.
Build your design in GNU Radio Companion, import it, and placeKYT turns it into a running bitstream on the cell array, with output back into GNU Radio's own waveform viewer. No HDL, no timing closure, no manual layout.
Watch data flow through the array and see which cells execute, instead of reading waveforms off a synthesized HDL netlist. Instruction-level debug (breakpoints, single-step, live register inspection) is in progress.
placeKYT maps your DSP block graph onto the 2D cell array, optimizes placement, and inserts routing automatically, so reconfiguring a signal chain is an edit-and-rebuild, not a re-layout.
Run the design against real signal data on a cycle-accurate model of the chip, and watch data flow through the fabric in real time.
Every parallel architecture needs software, and porting libraries by hand is what has historically killed them. By leveraging GNU Radio and its existing block library, Kyttar's entire block library is written by AI agents and held to a hard bar: each block must be proven equivalent to the live GNU Radio block it replaces, running on the placed and routed array. The GRCon paper counts 113 verified blocks, and the library keeps growing.
The most recent were built by an autonomous factory: each block dispatched to an isolated agent that implements, places and routes, verifies, and adds it to a working example. Those builds are instrumented, and the numbers below are the measured cost of producing a verified DSP block for a new architecture, taken from the 62 instrumented library-block builds reported in the GRCon paper.
| Metric | Result |
|---|---|
| Instrumented builds | 62 (61 verified, 1 quarantined) |
| Output tokens, median per block | 232k |
| Output tokens, whole campaign | 18.9M |
| Verified on the first attempt | 51 of 62 |
| Wall clock, median per block | 31 min |
| Verification tests in the suite | ~4,400 |
Verified means bit-exact against live GNU Radio where the arithmetic allows, and inside a tolerance derived from the quantization analysis where it does not. Every test must also be proven to fail when the block is deliberately broken, so the gates have teeth. The single quarantine is an honest negative result: the agent proved the block could not meet the bar, diagnosed why, and filed a reproduction instead of shipping it.
Costas loop, band-edge FLL, M&M timing recovery, LMS equalizer, AGC, RMS, CORDIC magnitude and argument.
RRC matched filter, frequency-translating FIR, rational resampler, delay lines, raised-cosine envelope shaping.
Hamming(7,4), Golay(24,12), CRC-16, block interleaver, LFSR scrambler, differential encode and decode, Varicode.
Streaming radix-2 FFT at 16, 32, 64 and 128 points; gated recurrent unit with a classifier head; sigmoid, tanh, dot-product MAC.
Chirp generator, symbol mapper, conjugate-chirp dechirp mixer, preamble sync, bin argmax.
Complex add, subtract and multiply, constant gain, N·log10, bit packing, byte logic, symbol mapping, slicers.
The easy workflow is possible because of what Kyttar is: a clockless, massively parallel cell array purpose-built for real-time DSP. This is the payoff under the hood.
No global clock. No clock distribution network. No clock skew. Each cell operates asynchronously, processing data the instant it arrives. The result: power proportional to activity, and no clock harmonics injected into sensitive analog and RF front-ends.
An array of identical compute cells, each with its own memory, ALU, and bundled-data communication with its four neighbors. No shared bus. No central bottleneck. Every cell runs its own program independently, in parallel.
Purpose-built for real-time DSP. Hardware multiply-accumulate. Q15 fixed-point arithmetic. Run many parallel receiver chains, demodulators, filters, mixers, decoders, simultaneously on a single chip.
Compose DSP functions by placing them spatially across the array. Changing the signal chain means loading new cell programs: no synthesis, no timing closure, no bitstream rebuild. Integrated with GNU Radio for real-world SDR workflows.
| Classical DSP | FPGA | Kyttar | |
|---|---|---|---|
| Parallelism | Limited (sequential core) | Massive | Massive (spatial cell array) |
| Programming model | C / assembly | HDL (VHDL / Verilog) | Function-level block placement |
| Build flow | Compile | Synthesis, place & route, timing closure, bitstream | Place & route in seconds; no synthesis or timing closure |
| Toolchain | Vendor or open compilers | Vendor tools; paid licenses for high-end parts | Open source (GPL), free |
| Power | Moderate | High (clock-tree floor) | Low (clockless, activity-proportional) |
| Clock harmonics into analog/RF | Yes | Yes | None (no clock) |
| Fault tolerance | None | Limited | Cell-level route-around (automation in progress) |
| Raw peak throughput | Lower | Very high | Lower on the SKY130 test chip; scales with node and array size |
The FPGA wins on raw peak throughput and decades of ecosystem maturity. Kyttar is built for a different combination: power that follows activity, a function-level programming model that skips HDL and timing closure entirely, and a toolchain that is open source end to end. These are architectural properties, not a benchmark: the first chip is a 130nm test chip, and a fair power comparison against an FPGA waits for a Kyttar part on a comparable node.
Sensors, telemetry, sub-GHz and mesh radios, and multi-mode devices that need to change modulation without changing the part. Several channels on one die, low cost, and power proportional to activity.
Many parallel channels of demodulation on one low-power chip. Spectrum monitoring, cognitive radio, and multi-mode receivers that reconfigure on the fly, straight from a GNU Radio flowgraph.
Low-SWaP spectrum awareness and command-and-control processing in a man-portable, power-constrained package. Reconfigurable in the field, and fault-tolerant, defective cells are routed around, for hard-to-reach and harsh-environment deployments.
Lattrex Inc. designs asynchronous parallel processors for real-time signal processing, a homogeneous array of self-timed cells that runs DSP functions in parallel, with no global clock.
Our first chip is a 120-cell test chip, taped out on the SkyWater 130nm process in 2026 using an open-source design flow, with first silicon expected back at the end of November 2026. It exists to prove the asynchronous architecture on real silicon before capital goes into a smaller node. The architecture is process-portable, and production parts are planned on a 12nm-22nm-class node with a licensing or manufacturing partner.
Lattrex is a Delaware C-corporation operating in Tennessee, registered in SAM.gov and pursuing non-dilutive federal R&D funding. We submitted a Navy STTR Phase I proposal in 2026 in partnership with Virginia Tech's MICS Group.
Designed the cell architecture, instruction set, and RTL. Built the cycle-accurate simulator, the DSP block library, the GNU Radio integration, and the placeKYT development environment. Took the design from concept through tape-out solo.
LinkedIn →Six characters. One square. The complete architecture of a processor.
It started with a thought experiment: what is the simplest possible processor that can communicate with its neighbors? The answer was the flip-jump processor—a single-instruction machine that flips a bit and jumps to an address. The \ is flip. The ‾ is jump.
But simplicity alone isn't enough. The right balance came from adding just what was necessary. The = represents memory operations and comparisons. The \ becomes transformation. The + is arithmetic. The .* represents on-board memory—the cell stores its own program and data, executing any combination of instructions until it finally JUMPs to a neighbor.
The square represents the cell itself: self-contained, four faces, four neighbors. Everything the cell does and everything it is can be described with this diagram.
But there is more than meets the eye.
The five left-side characters form a face looking right—. is the ear, * the eye, \ the nose, = the mouth. The cell is awake. Active. Looking forward.
Now look at the right-side characters, ignoring the .*—another face, but with its eye closed. The cell at rest. This is the asynchronous nature made visible: fully active or fully off, instantly. No idle state. No wasted energy.
Simple units. Complex emergence. Like fungal networks or ant colonies—individual cells following simple rules, together producing behavior far greater than the sum of their parts.
Nothing more than necessary. Nothing less than sufficient.
Lattrex Inc.
1143 Oak Ridge TPKE
STE 107A #310
Oak Ridge, TN 37830